My AI Toolkit, Four Weeks In: Models, Harnesses, and Everything Else I Actually Reached For
A no-marketing inventory of the models, agent harnesses, and supporting tools I used day-to-day over the last four weeks — what each is good at, what it isn't, and what I'd reach for first next time.
Every “AI tool” listicle reads the same. Twenty bullets, each with a vendor blurb, none with the question I actually want answered: did the author keep using it after week one?
This post is the opposite. Over the last four weeks I shipped a personal site rewrite, drafted an essay series on agent-ready codebases, and ran an Engineering Manager day job. Below is the honest inventory — what I reached for repeatedly, what I bounced off, and what each thing is genuinely good at.
Models
Claude Opus 4.7 (1M context)
Default for any task that touches code I care about. The 1M context window is the feature I underestimated most before using it — it changes the calculus on “do I bother loading the whole repo.” Strong at refactoring, very strong at following a CLAUDE.md, occasionally over-cautious about destructive actions (which is mostly a good thing — it saved me from a direct push to main more than once).
Claude Sonnet 4.6
The workhorse when latency matters more than depth. Drafts, short edits, fast iteration on the homepage components. ~80% of Opus quality at a fraction of the wait.
Claude Haiku 4.5
Available but didn’t actively pick it this cycle — the work was either deep enough to want Opus or fast enough that Sonnet’s latency was already fine. Earmarked for sub-agent fan-out next time, where speed beats depth.
GPT-5 / ChatGPT (rotating subs)
Yes, two subscriptions on automatic rotation — bluntly, to dodge rate limits during heavy days. ChatGPT stayed in the toolkit for non-coding work and for the occasional second opinion when Claude got stuck in a local minimum. Not my default driver, but a useful sanity check.
The OpenCode / Z.AI roster
This is where things got interesting. Inside OpenCode I bounced between:
- Big Pickle (OpenCode Zen)
- GLM-5-Turbo (Z.AI Coding Plan)
- Kimi K2.6 (OpenCode Go)
- DeepSeek V4 Pro (OpenCode Go)
- Qwen3.6 Plus (OpenCode Go)
None of these replaced Claude as my default. But — and this is the important bit — they were excellent for parallel comparison runs (more on that below). When you have the same prompt and five different model lineages chewing on it, the disagreements are the signal. Kimi K2.6 and DeepSeek V4 Pro punched above their tier on focused, well-scoped tasks. GLM-5-Turbo was the surprise — competitive on shorter prompts, struggled on longer plans.
Harnesses
Claude Code
Where the majority of my coding sessions happened. The features that earned their keep, in order of how often I leaned on them:
- Hooks —
SessionStart,PreToolUse,PostToolUse. Wrote a full essay on why these pay for themselves; short version: deterministic context > prompt engineering. - Sub-agents —
Explorefor read-only research,Planfor design work, general-purpose for fan-out. Saved an enormous amount of main-context bandwidth. - Skills — invoked by
/<name>. Cleaner than stuffing instructions intoCLAUDE.md. design.md+CLAUDE.md— the project memory pattern. Not a Claude Code feature exactly, but the harness makes it work.
OpenCode (with OpenCode + Z.AI subs)
The second harness in heavy rotation. The model picker (Big Pickle, GLM-5-Turbo, Kimi K2.6, DeepSeek V4 Pro, Qwen3.6 Plus, and friends) is what made it click — not because any one of those models beats Opus, but because comparing across models on the same prompt is a different kind of feedback loop. You stop treating any one model’s output as gospel.
Multica
The orchestration layer I didn’t know I needed until I had it. Multica treats agents as actual team members — they appear in assignee dropdowns, claim tasks, report progress, and post completion notes alongside humans. The real test came when I used it to migrate an app from SQLite to PostgreSQL: I planned the migration in CLAUDE.md, broke it into a queue of tasks (schema, data, dialect-specific query rewrites, integration test fixes), and let agents work through them while I watched the unified timeline. The benefit isn’t “magic migration” — it’s that the lifecycle is visible and resumable. If an agent gets stuck on a foreign-key constraint, it surfaces; if a step fails, I re-enqueue rather than restart. Multica also unifies the runtime across ~11 coding tools (Claude Code, Gemini CLI, etc.), so the model question stays orthogonal to the workflow question.
Paperclip
Adjacent to Multica — same shape (agent orchestration), different altitude. Multica feels like a team project board; Paperclip feels like an org chart with budgets, roles, and approval gates. I touched it lightly this cycle; it’ll get a proper trial when the work shape is “run a small autonomous business function,” not “ship a feature.”
Hermes
In rotation for lighter, faster tasks where I wanted a second opinion without the cost of a full Claude Code session. Useful as a quick reality check.
Claude on web (claude.ai)
For non-coding work — drafting, brainstorming, the occasional artifact. Different mental model from Code: less “give me a file” and more “think with me.”
IDE-integrated harnesses (Cursor, Windsurf, Zed, Aider, Cline, Continue)
Didn’t lean on these this cycle. Between Claude Code and OpenCode the CLI surface covered enough ground that the friction of switching IDEs never paid off. If your work is dominated by tight inner-loop edits inside a single file, an IDE-integrated harness probably wins. Mine wasn’t.
The workflow that mattered most: plan once, run in parallel
This is the pattern that changed how I worked the most in the last four weeks:
- Plan in
CLAUDE.md. Open a session with Claude Code, work out the full plan for the change — what files, what order, what tests, what acceptance criteria. The output isn’t code yet, it’s a structured plan. - Convert the plan into a set of prompts. Each prompt is one self-contained slice — enough context to be runnable on its own, narrow enough not to need follow-up clarification.
- Fan them out across models. Hand the prompts to different models inside OpenCode — Kimi K2.6 on one, DeepSeek V4 Pro on another, GLM-5-Turbo on a third, Claude on the rest. Parallel, not serial.
- Compare the outputs. Where models converge, the answer is likely robust. Where they diverge, that’s the spot to think harder — usually the prompt was ambiguous, or the problem is genuinely judgement-shaped.
- Promote the best slice into the main branch via Claude Code.
Two things this gives you that single-model flow doesn’t:
- Cheap diversity of approach. You see three or four different shapes of solution for the price of writing the prompts once.
- A built-in bullshit detector. Five models confidently producing five different answers is data — usually meaning your problem isn’t as specified as you thought.
The pre-condition is that your prompts have to be good. Vague prompts produce vague disagreement, which is noise, not signal. The time you save on writing code, you spend on writing prompts — and that trade has been worth it.
Supporting tools
mise
Default tool manager for language runtimes (Node, pnpm) and most CLIs. Brew is reserved for the narrow cases where mise can’t help: system services (brew services), native libraries that compiled gems link against, and shell replacements. The agent benefits indirectly — mise use -g <tool> is a deterministic instruction it can issue without reaching for a system-wide install.
gh CLI
For PR creation, merging, run inspection. Every “push and watch CI” loop in the last four weeks went through gh run watch or gh pr view. The harness using gh is also what unlocked the next item.
Automated release notes from GitHub releases
A small piece of automation that quietly paid off all month: a workflow that watches GitHub releases and generates user-facing release notes from the underlying PR titles, labels, and merged commits — drafted by an agent, posted as the release body, edited by a human in under a minute. The agent does the grunt work (categorising features vs fixes, picking up the right links); the human keeps the voice. Net result: every release ships with notes, not just the ones I have energy to write.
rehype-pretty-code + one-dark-pro
Shiki-based syntax highlighting in the blog build. Not an AI tool, but it’s what made the AI-related posts actually readable.
MCP servers
Several connected — Atlassian, Notion, Gmail, Drive, Slack, Calendar — but I didn’t lean on any of them for the work that shipped this cycle. The honest take: MCP earns its place when the agent’s job is the integration (triaging a Jira queue, summarising a Notion page, drafting an email). For repo-bound work, the file system + gh + a good CLAUDE.md did more for me than any MCP server. Worth revisiting when the work shape changes.
Patterns that mattered more than the tools
CLAUDE.mdas a contract, not a prayer. Rules backed by tooling, not aspirations.design.mdas the visual brain. Tokens, archetypes, motion principles — one place, one truth.- Plan once, prompt many, run in parallel. The workflow above. Don’t treat the plan and the prompts as the same artifact.
- Session-start hooks for state. Branch, last commit, in-flight PRs, dev server status — surfaced before the agent reads the first instruction.
- Sub-agents for context hygiene. Anything read-only or speculative goes to a sub-agent so the main context stays clean for the work that ships.
- Automate the chores that erode discipline. Release notes is the canonical example — left to humans, they slip; left to a fully automated bot, they read like a robot wrote them. The middle ground (agent drafts, human polishes) is the one that actually sticks.
What I’d reach for first next time
- Claude Opus 4.7 in Claude Code, with a tight
CLAUDE.md, adesign.md, and session-start hooks. Default stack, earned that spot every day. - OpenCode for parallel model comparison on any plan complex enough to have ambiguity. The cost of running five models on the same slice is trivial; the cost of shipping the wrong shape isn’t.
- Sonnet 4.6 for anything where I’d otherwise wait for Opus. The latency win compounds across a session.
This list is a snapshot — 13 May 2026. Half of it will be wrong in two months. That’s fine. Tooling is downstream of taste; what you reach for says more about how you work than what you use.
Keep reading
Agent Config, Installed Tool, and Live Behavior Are Three Different Things
A model or workflow can be correct in source and still be absent from the installed runtime. Verify each layer before claiming it works.
Running Independent AI Research Trials
Two isolated research environments can work from the same source material while keeping their analysis independent and reviewable.
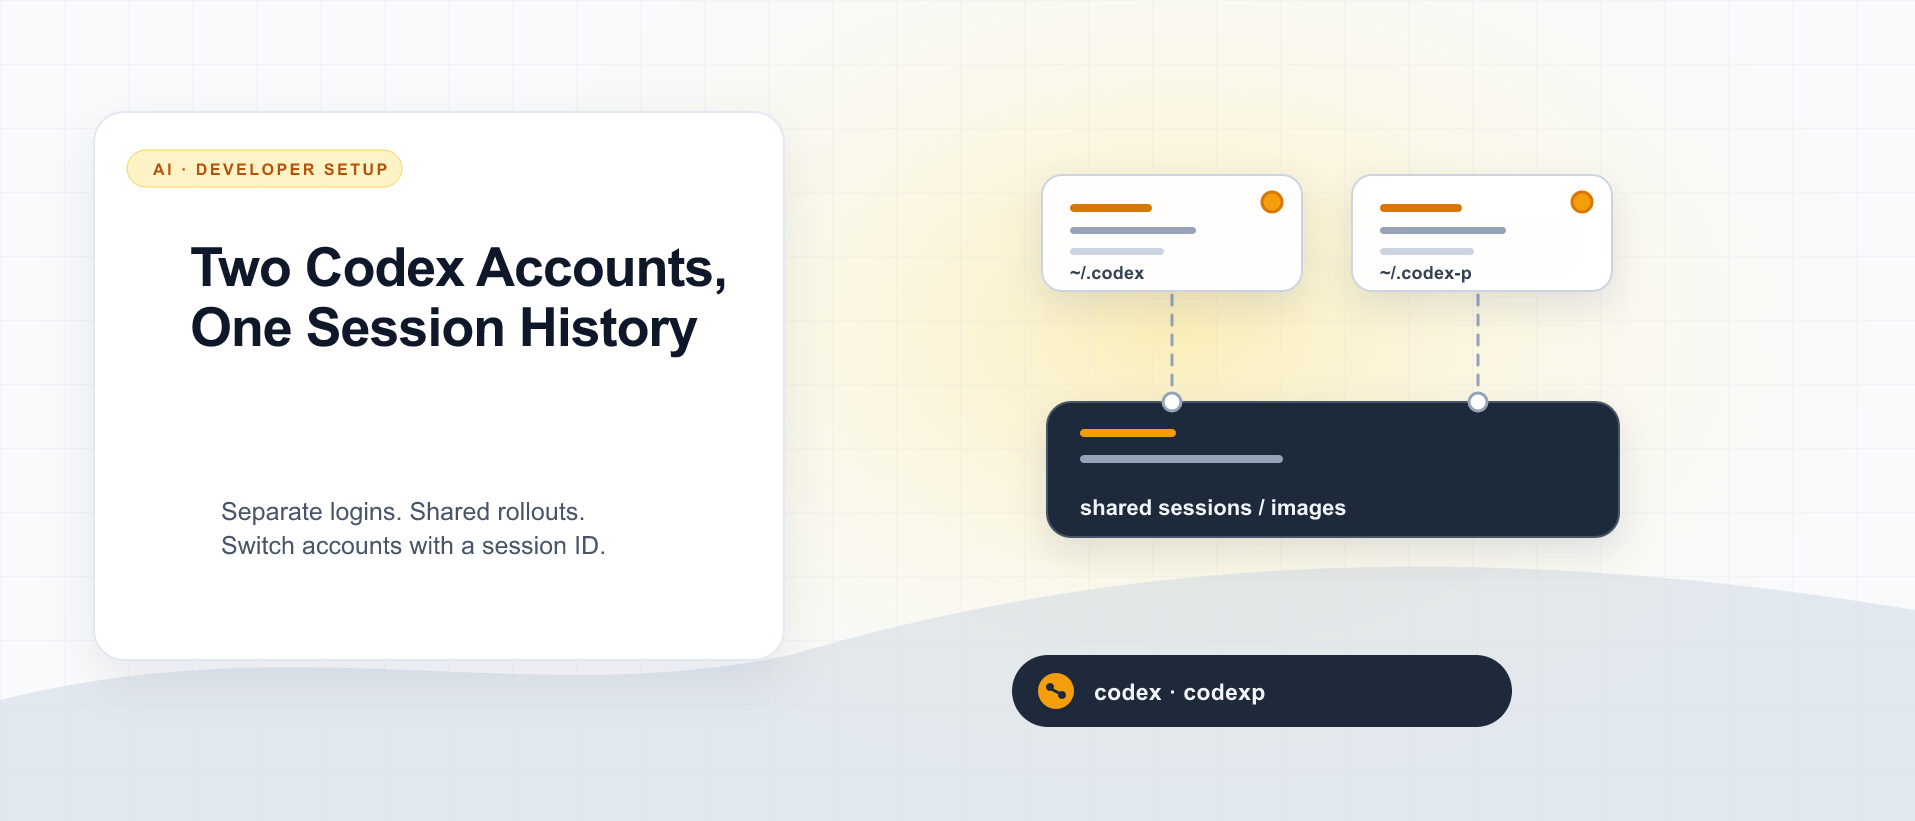
Two Codex Accounts, One Session History
Use CODEX_HOME for a second Codex login, then share only the session files you need to resume by ID. Here is the setup I use, what stays separate, and what I actually verified.
What did you take away?
Thoughts, pushback, or a story of your own? Drop a reply below — I read every one.
Comments are powered by Disqus. By posting you agree to theirterms.