Why My NVMe Benchmark Was Misleading
A slow region on one SSD looked like wear. Matching offsets, data state, temperature, and concurrent load changed the diagnosis.
One NVMe drive seemed to read at roughly 3.2–3.6 GB/s in some regions, while another drive in the same host reached around 5.3 GB/s. I wondered whether the slower areas had worn out or whether heat was throttling the drive.
The first benchmark did not answer that question. It compared regions with different contents.
The comparison was not equivalent
We sampled matched logical offsets and found that the slower regions on the first drive held varied data. Its zero-filled region read at about 5.3 GB/s. The comparison drive’s sampled regions were zero-filled too.
That meant the original headline comparison mixed two conditions: populated data on one device and zero-filled data on the other. Storage controllers, compression behavior, flash translation, caching, and the host’s I/O path can all affect what a read experiment measures. A logical offset is not a window onto a specific physical NAND location.
The benchmark needed to control more than the drive model and file size. It needed comparable offsets, data state, access method, and timing.
Check the wear and thermal evidence separately
The drive reported zero percent endurance used, no media errors, no error-log entries, and no time above its warning or critical temperature thresholds. During a short direct read, its temperature rose from 41°C to 44°C. That did not support either worn-out areas or thermal throttling as the explanation.
Those counters do not prove that a device can never fail. They do make “this region is worn out” a poor conclusion from a short read test.
We then ran concurrent reads with identical offsets and workload sizes on both drives. That reproduced a difference under the paired condition, but it still did not make every earlier number comparable. The subsequent SSD replacement and clone gave us a fresh baseline, while leaving the removed device disconnected because cloned disk identifiers can collide.
What I changed in the benchmark method
For a regional comparison, the procedure now records:
- exact device model and controller identity;
- PCIe link generation and width;
- SMART wear, error, and temperature counters;
- exact byte offsets and read sizes;
- whether the sampled regions contain similar data;
- direct versus cached I/O;
- single-drive and simultaneous-drive results;
- temperature before and after the run.
The read script is bounded and uses direct I/O, which helps reduce page-cache effects. It still measures a particular workload at particular regions. It is not a sustained write rating, application latency test, or prediction of a drive’s remaining life.
Don’t turn a surprising number into a story too soon
If a number looks wrong, first reproduce the conditions that produced it. A separate quick test at another offset can miss the effect entirely. Then ask what the result actually measures and which explanations the available evidence can eliminate.
In this case, the first benchmark suggested a damaged region. The data-state mismatch and SMART/temperature checks weakened that explanation. A matched concurrent run showed a real performance difference under that narrower setup, but did not establish physical wear.
That is a less dramatic conclusion. It is also the one the evidence supports.
Keep reading
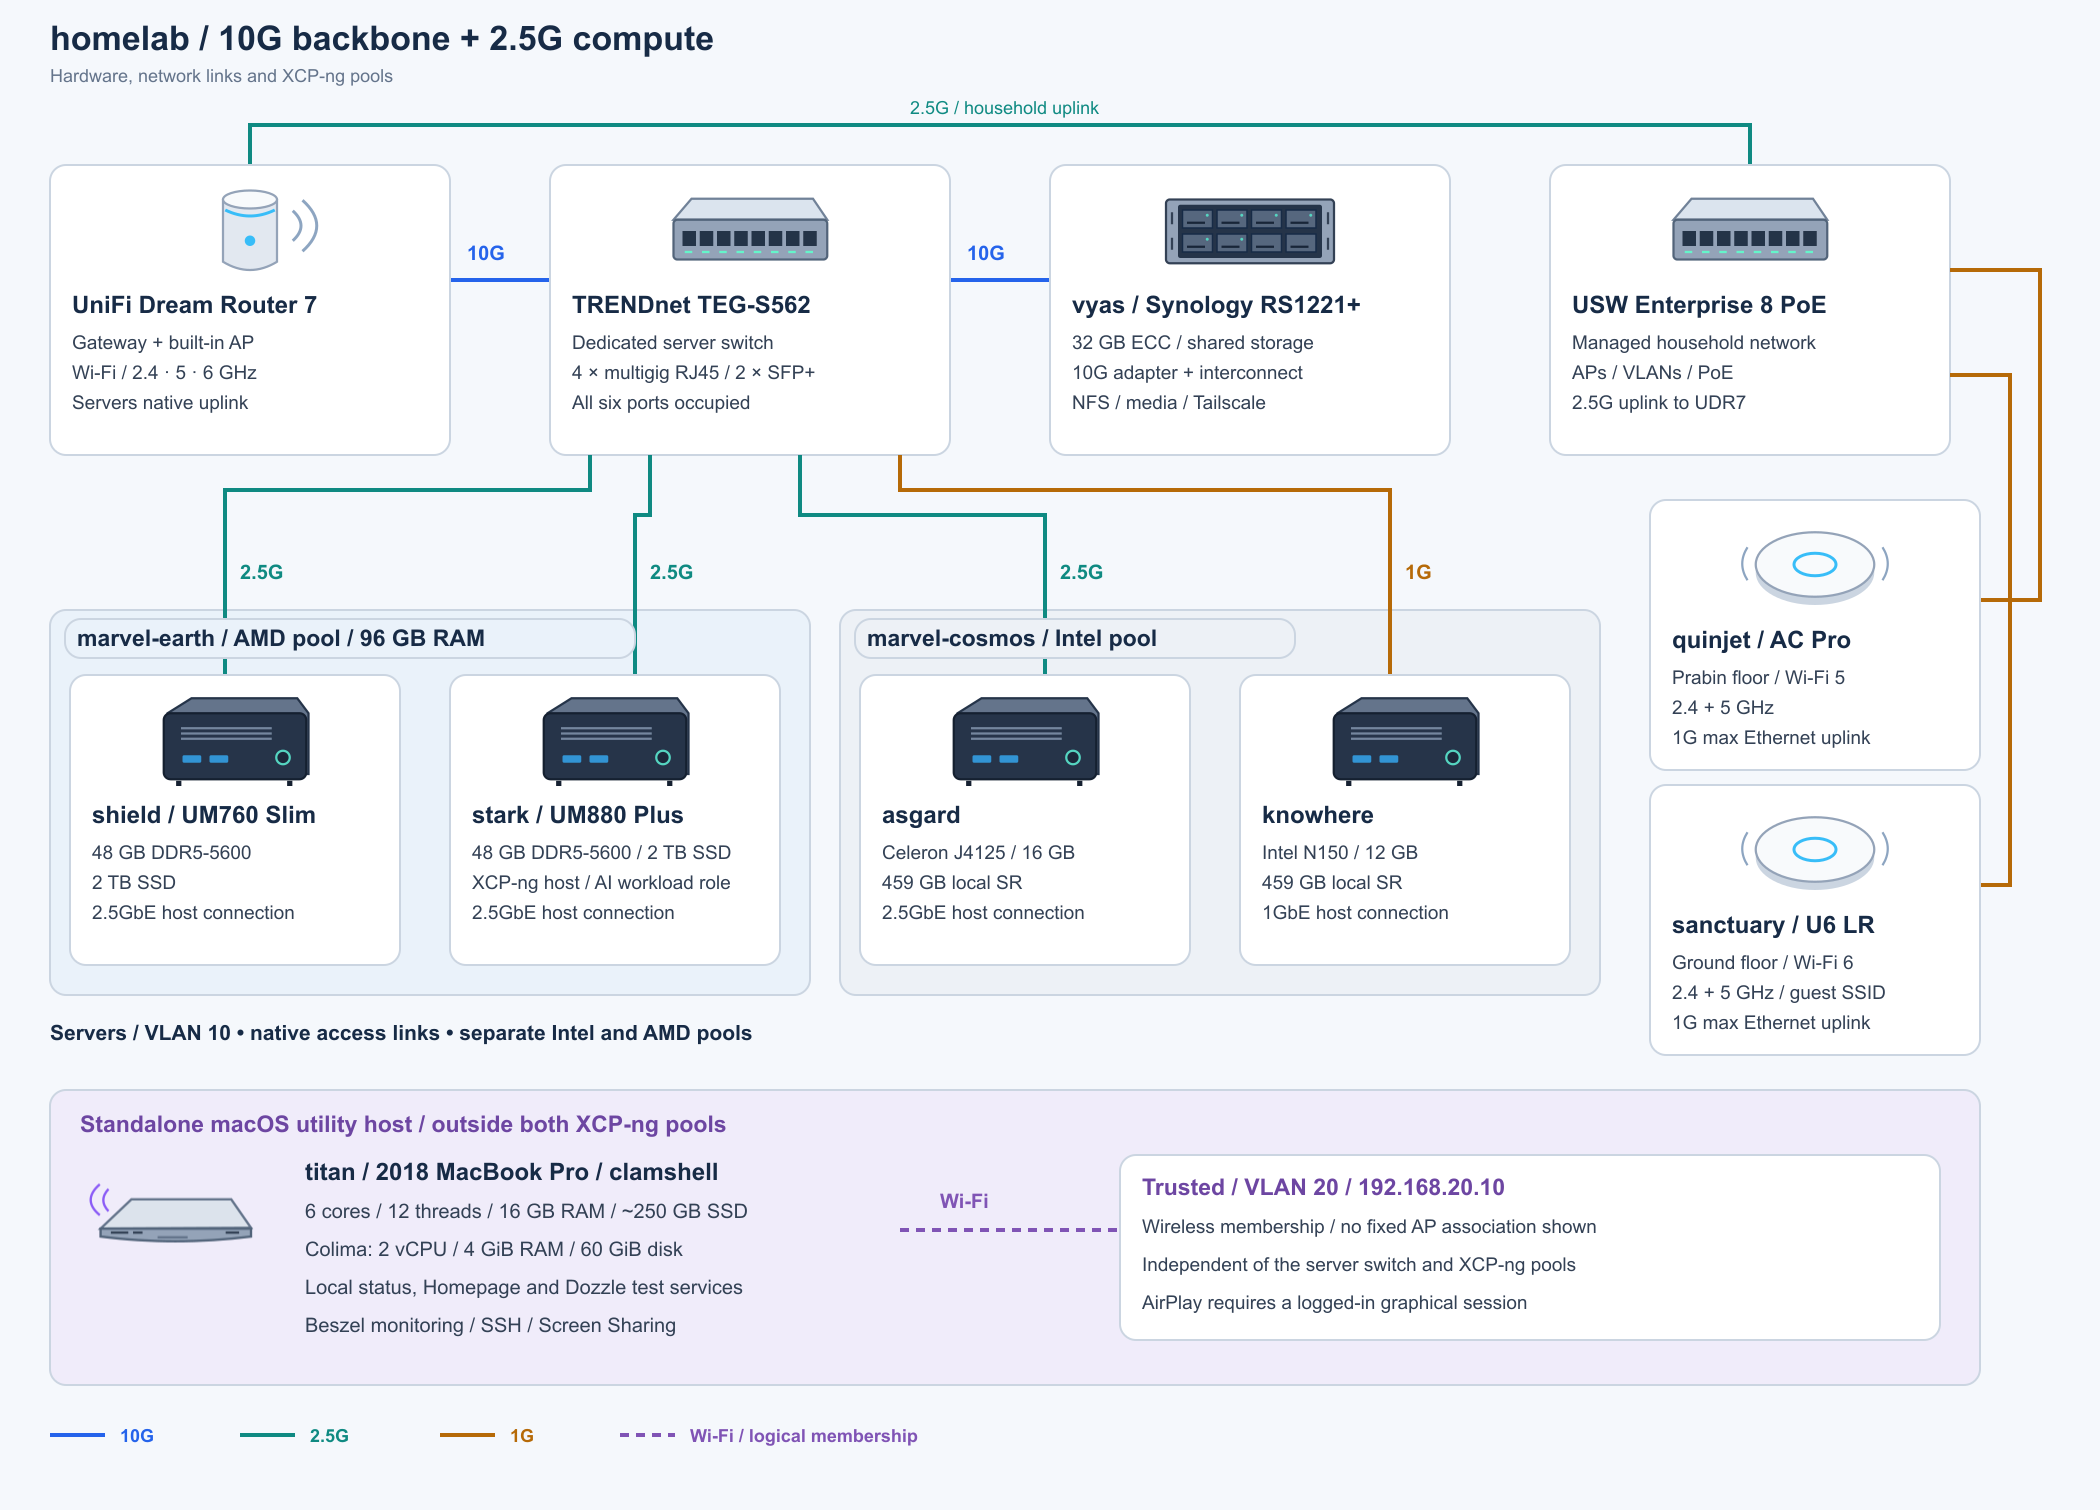
My Homelab Goes Multigig: 10G Networking and 160 GB Across Two Minisforum Hosts
A dedicated 10G server backbone, 2.5G compute links, and two Minisforum hosts: Talokan with 96 GB for XCP-ng and Shuri with 64 GB for Ubuntu, gaming and local AI.
Letting Coding Agents Build It: An Orchestrator, Parallel Lanes and Verification Over Trust
Much of the Campsite work in this series was implemented by coding agents in parallel worktrees, coordinated by another agent. What made that work was re-checking every result before it merged, and learning from the times it went wrong.
From MySQL to PostgreSQL with Patroni HA: A Migration in Progress
Campsite is moving from MySQL to PostgreSQL. The test suite now passes on both, a small Ruby copier replaced pgloader, and a Patroni cluster is live across three hosts. Production still runs on MySQL, and here's why.
What did you take away?
Thoughts, pushback, or a story of your own? Drop a reply below — I read every one.
Comments are powered by Disqus. By posting you agree to theirterms.