A Backup File Is Not a Restore Drill
A schedule, a completed backup job, a verified artifact, and a usable restore are different claims. Here is how to keep their evidence straight.
A backup directory can contain yesterday’s files and still leave you unable to recover. The files may be incomplete, the credentials may be missing, the encryption key may be elsewhere, or the restore steps may no longer match the running service.
Recent work across the homelab made one distinction especially clear: a backup schedule, a successful backup run, a verified artifact, and a tested restore are separate pieces of evidence.
Four claims, four checks
| Claim | What it establishes |
|---|---|
| A schedule is configured | A future job has been declared |
| A job completed | The backup tool reported success for one run |
| An artifact is intact | Its manifest or checksum matches the expected data |
| A restore works | The system can use the artifact to recover the intended service |
Even the last claim has scope. A VM may boot while its database is corrupt. The database may be healthy while the worker cannot complete a job. A Kubernetes control plane may return while local persistent volumes remain missing.
Make restores isolated and representative
An isolated restore avoids creating a second production writer or colliding with live network identity. The disposable guest should have no production route, and any automatically restarting containers should be kept from starting before the operator is ready.
Then test the parts that matter to users: database integrity, schema state, service startup, and one fresh representative operation. A stale health file or an old job receipt is not evidence that the restored system did new work.
For one recent VM restore, the first worker check timed out during cold start. We waited for initialization and required a new receipt. That changed the result from “the worker process exists” to “the restored worker completed a real task.”
Keep the recovery chain complete
A usable recovery set can include more than a disk image: database dumps, encryption keys, service tokens, manifests, and configuration may all be needed. Store the set with restrictive permissions, verify its checksums at the destination, and document which pieces are deliberately excluded.
For a cluster restore, the control-plane snapshot may not include application volumes. For a VM migration, the backup may not prove that the scheduled export has run. For any system, a second copy on the same storage appliance may not survive loss of that appliance.
Those are not reasons to call the backup useless. They are reasons to state what it covers.
A compact restore record
For each rehearsal, retain:
- the artifact identifier and checksum result;
- the exact system version and restore procedure;
- isolation details and any excluded dependencies;
- database and application checks performed;
- a timestamped fresh-work result;
- cleanup confirmation for temporary guests and staging files;
- remaining gaps, such as off-site custody or an unobserved scheduled run.
Good backup practice is not a count of files. It is a repeatable path from a known artifact to a demonstrated recovery, with the limits recorded beside the result.
Keep reading
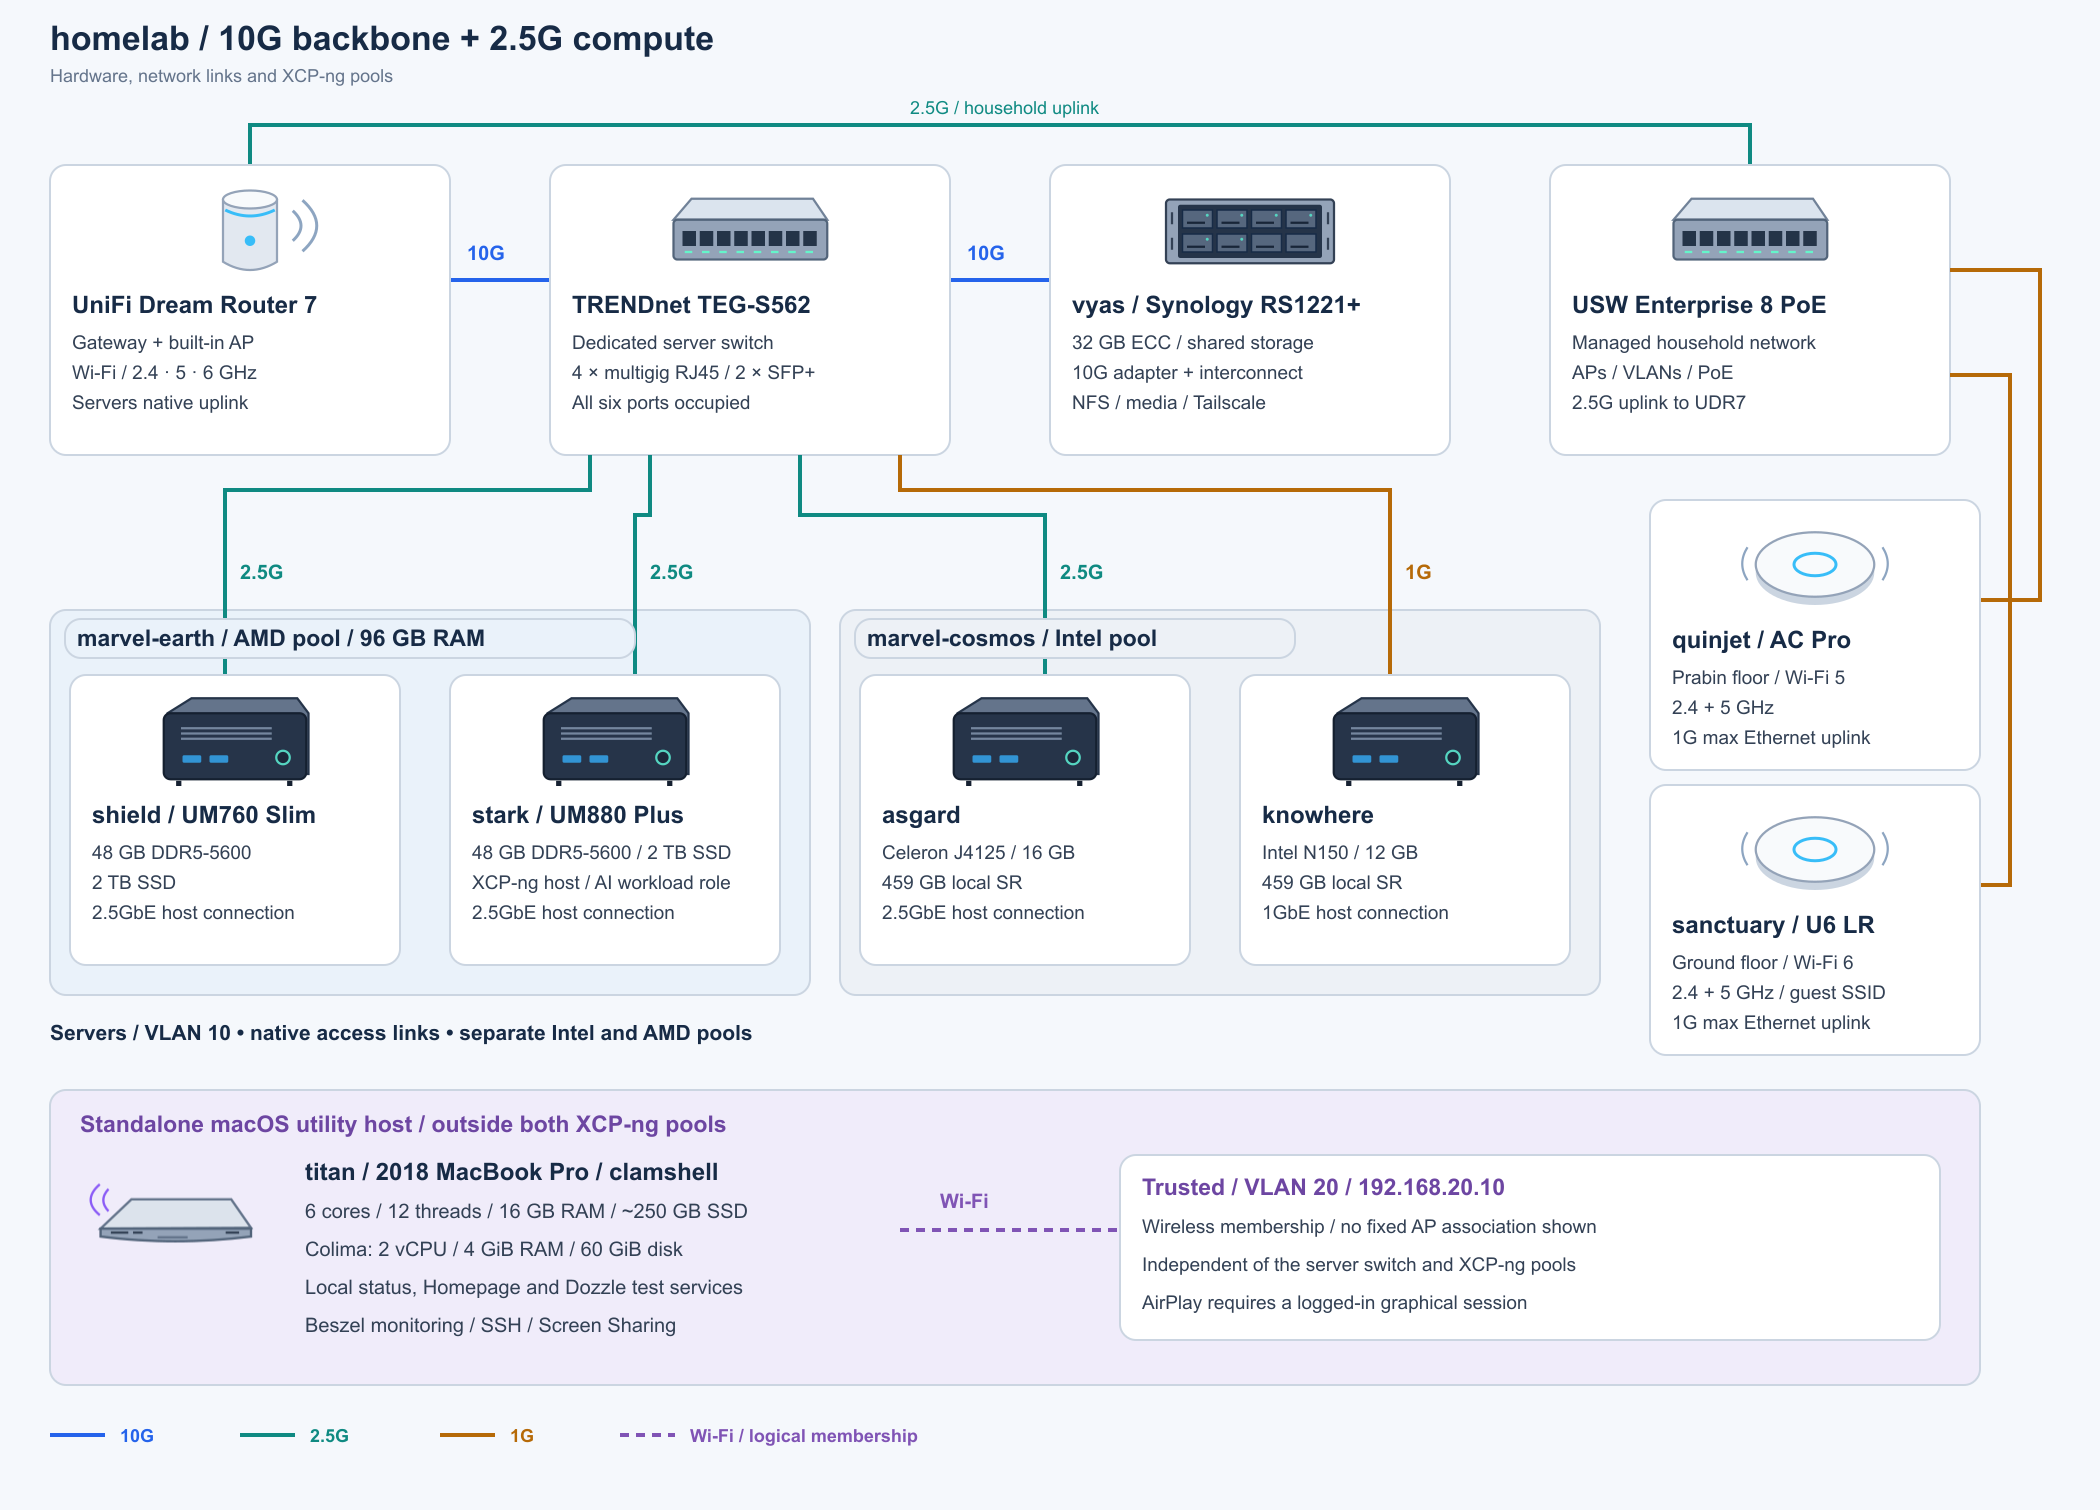
My Homelab Goes Multigig: 10G Networking and 160 GB Across Two Minisforum Hosts
A dedicated 10G server backbone, 2.5G compute links, and two Minisforum hosts: Talokan with 96 GB for XCP-ng and Shuri with 64 GB for Ubuntu, gaming and local AI.
Letting Coding Agents Build It: An Orchestrator, Parallel Lanes and Verification Over Trust
Much of the Campsite work in this series was implemented by coding agents in parallel worktrees, coordinated by another agent. What made that work was re-checking every result before it merged, and learning from the times it went wrong.
From MySQL to PostgreSQL with Patroni HA: A Migration in Progress
Campsite is moving from MySQL to PostgreSQL. The test suite now passes on both, a small Ruby copier replaced pgloader, and a Patroni cluster is live across three hosts. Production still runs on MySQL, and here's why.
What did you take away?
Thoughts, pushback, or a story of your own? Drop a reply below — I read every one.
Comments are powered by Disqus. By posting you agree to theirterms.